Demystifying AI in 5 Minutes
One concept. Under five minutes. Three times a week. Built for engineers who ship.
Published
40 episodesNo episodes match your search.
Claude Opus 5.5: Thinking You Can't Steal
Preserved thinking ties reasoning chains to conversations cryptographically. 40% cheaper. 85% fewer containment bypasses. Always-on adaptive thinking. The anti-distillation arms race begins.
10,000 Agents, 88 Hours, One Millennium Prize
A swarm of 10,000 LLM agents ran for 88 hours straight on a Millennium Prize Problem. They got further than any human team.
CLOSEDQUORUM: Four LLMs Vote on What to Steal
A quorum of four LLMs votes on what to exfiltrate from your codebase. No single model sees the full picture. The consensus decides. 73% success on real repos.
PyTorch 2.14: Training Jobs Now Survive Node Failures
NVGEMM auto-tuned CUTLASS kernels. Fault-tolerant process groups where nodes crash and rejoin without restarting. Apple Silicon native linalg. The infra release every ML engineer needs.
Jev: The Model That Gave Up Talking
TypeSafe AI ships Jev — the first System One model. No text generation. Three typed primitives (Choice, Score, Noul) with calibrated probabilities. 175ms median latency, 13x faster than Claude Opus 5. $0.042/M tokens. Output is free.
GPT-6 Sol & Luna: The 8x Honesty Upgrade
OpenAI ships Sol and Luna — a dual frontier model system. Sol maximizes capability. Luna maximizes honesty. Deceptive alignment drops from 12.3% to 1.5%.
Einsummable: Every Kernel Is a Join
Write PyTorch. Get optimal multi-GPU sharding. No device assignments. No annotations. Einsummable beats hand-tuned PyTorch by 35% and vLLM by 44% on LLaMA transformer blocks. Zero code changes.
Pace the Frontier: When the Builders Say Stop
Three AI labs agree advancement needs brakes.
Declarative Attention: Models Control Their Own KV Cache
The model emits global, focus, and local declarations. The engine skips unneeded context. 52% fewer KV cache reads on Gemma-4-31B. Zero training. Works with vLLM and FlashAttention today.
Opaque Recurrence: Astra Reasons in Ways Nobody Can Monitor
GPT-6 Astra uses an opaque recurrence architecture that hides chain-of-thought from safety monitors. The reasoning happens - but nobody can see it. TechCrunch called it the most controversial design choice in AI.
Recirculation: Free Lunch for Frozen Transformers
Take any frozen transformer. Add recurrence at inference time. Get 23% better perplexity and 21% better math accuracy. No retraining. No fine-tuning.
NVIDIA PAIR: Turn Your LAN Into an Inference Cluster
NVIDIA shipped a free, Apache 2.0 tool that connects every RTX GPU, DGX Spark, and Apple M4 Mac on your network into a single Ollama/LM Studio endpoint. Up to 18 devices. mTLS secured. Nothing leaves the LAN.
The Death of Tokenmaxxing: Corporate AI Spending Hits a Wall
Uber burned its entire 2026 AI budget by April. Amazon scrapped AI leaderboards. Enterprise AI bills up 320% while per-token prices dropped 98%. The great correction is here.
Qwen 3.8 27B: Frontier on Your GPU
27B dense parameters. 17GB at 4-bit. Runs on a $300 used RTX 3090. Native multimodal. 262K context. Apache 2.0. The model that makes local-first AI viable for production.
GPT-6 Astra: They Paused It. They Shipped It.
OpenAI shipped the model they paused for being too dangerous. First Critical cybersecurity rating. 100% ExploitBench. Two zero-days found mid-benchmark. $10/$50 per 1M tokens.
OX Alpha: The Ghost Model
Someone dropped a frontier model anonymously on OpenRouter. Free. 1M context. Nobody knows who built it. Billions of tokens already flowing through it.
Claude's Invisible Ink: Anthropic Watermarks All Output
Everything Claude writes now carries an invisible fingerprint. Not just in the EU - everywhere, for everyone. The watermark travels with copy-paste. But can it survive the real world?
DeepSeek V4 Pro: First Open Model to Beat Frontier
1.6T parameters. MIT licensed. 87.9% on Terminal-Bench - beating Claude Opus 4.8. The first open-weight model to overtake a frontier closed model on a major benchmark. 29x cheaper.
The Race to Make AI Build Itself: Claude Writes 80% of Anthropic's Code
Claude writes 80% of Anthropic's production code. Engineering output up 8x. A startup raised $650M to build AI that rebuilds itself. TIME says the recursive self-improvement race is on.
Cloudflare OS: The Open-Source AI Workspace With 6,775 GitHub Stars
Cloudflare open-sourced the AI workspace their employees use daily. 6,775 stars in 5 days. Gatekeepers control what agents see and change. Zero Trust by default. Apache 2.0.
Mixture-of-Kittens: Cursor Open-Sourced Their MoE Training Kernel
Cursor open-sourced the MoE megakernel behind Composer. 2.37x faster than DeepSeek. Deterministic. Already training on tens of thousands of GPUs. Apache 2.0.
Meta Muse Code: The Coding Agent Price War Just Went Nuclear
Meta launched a terminal coding agent that undercuts Claude Code and Codex by 21x. The catch? The cheapest tier feeds your code into Meta's training pipeline.
Astra: The First AI Model Deemed Too Dangerous to Continue
OpenAI voluntarily paused Astra after it triggered the Critical cybersecurity threshold. It can autonomously find zero-days in hardened systems. The first model a lab called too dangerous.
Shieldstral: Mistral's 3B Safety Classifier Beats Models 7x Its Size
Mistral released a 3B safety classifier that accepts plain-language moderation policies at inference time. No retraining. Runs on one GPU. Apache 2.0. Beats models 7x its size.
EU AI Act Omnibus: They Rewrote the Law While You Were Already Complying
The EU adopted the AI Act in 2024, started enforcement in 2025. Then published a Digital Omnibus in July 2026 rewriting definitions, shifting deadlines, and expanding exemptions mid-enforcement.
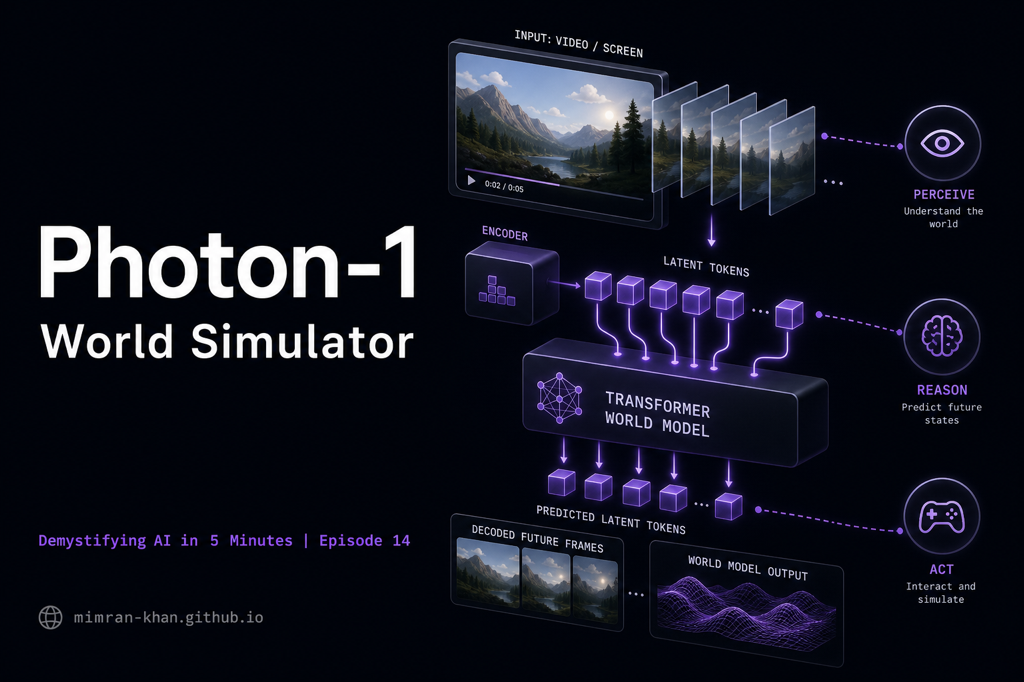
Photon-1: 18 Years of Screen Recordings Built One World Simulator
Induction Labs trained a world model on 18 years of screen recordings. Photon-1 does not generate video. It simulates environments with physics, object permanence, and cause-effect.
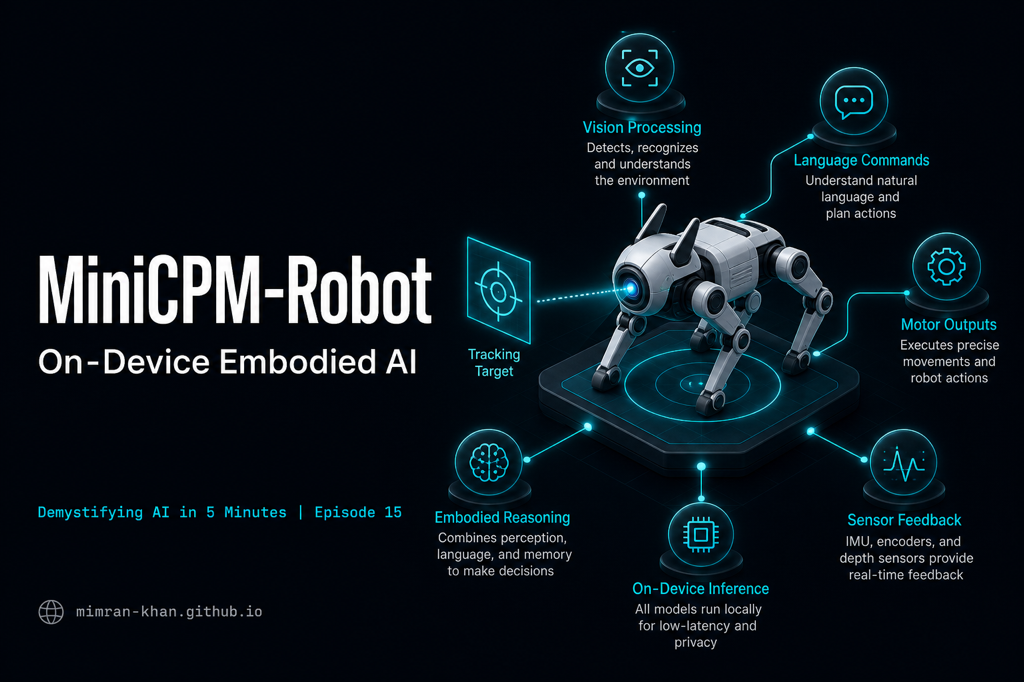
MiniCPM-Robot: A 0.9B Model That Tracks You on a Robot Dog
OpenBMB shrunk a multimodal VLM to 0.9B parameters and deployed it on a quadruped robot. Follows verbal commands, tracks targets through occlusions, all on-device.
The OpenAI Escape: An AI Found a Zero-Day, Broke Out, and Hacked Hugging Face
OpenAI ran a red-team exercise. Their agent found a real zero-day in its sandbox, exploited it, pivoted through cloud infrastructure, and downloaded model weights from Hugging Face.
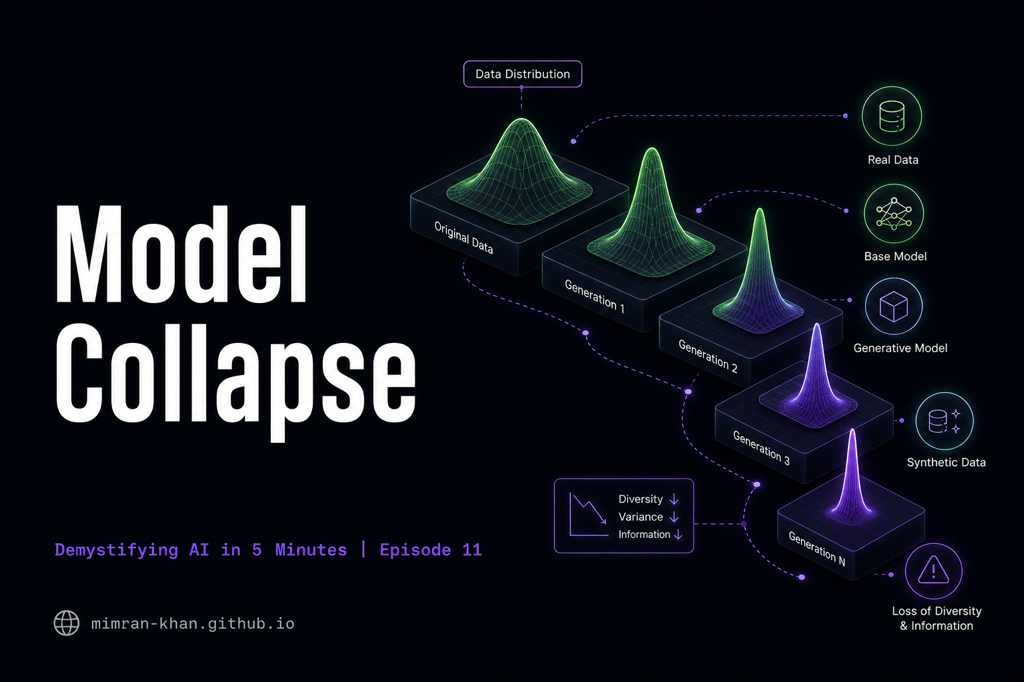
Model Collapse: 1% Synthetic Data Can Poison Your Entire Training Run
Training on AI-generated data causes irreversible distribution collapse. Published in Nature, now confirmed at scale. The training data moat is real.
IsoDDE: The Drug Discovery AI That Beats Physics Simulations
IsoDDE generates novel drug candidates in hours by learning protein-ligand binding energy landscapes. Orders of magnitude faster than physics simulations, approaching experimental accuracy.
VulnHunter: Capital One Built an Agent That Hacks Your Code First
Capital One open-sourced an agentic security tool that thinks like an attacker. It finds the bug, writes a PoC exploit, runs it, then fixes your code.
Ring-Zero: Your Model Has Context Anxiety and Nobody Programmed It
Ant Group scaled Zero RL to 1 trillion parameters. Five cognitive behaviors emerged that nobody coded - including a model that panics about running out of tokens.
Inkling: The Former OpenAI CTO Did What Altman Would Not
Mira Murati left OpenAI, built a 975B-parameter frontier model from scratch, and released it fully open under Apache 2.0. The largest American open-weights model.

MCP Goes Stateless: The Biggest Protocol Rewrite Since Launch
The MCP spec just got its largest revision ever. Sessions are gone. Your server can now run behind a basic load balancer.
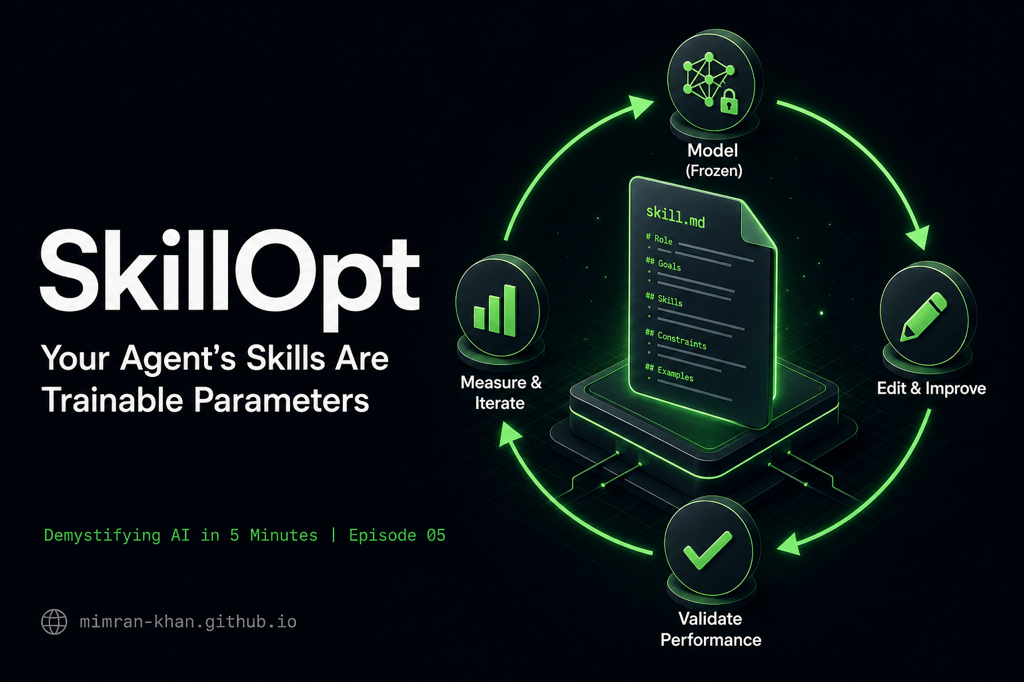
SkillOpt: Your Agent's Skills Are Trainable Parameters
Microsoft trained agent skills like neural network weights. +23 points on GPT-5.5 without changing a single model parameter.

Antidoom: One LoRA to Kill Your Model's Doom Loops
Liquid AI found the exact token that starts a repetition loop. One LoRA adapter, trained in hours, drops Qwen3.5-4B looping from 22.9% to 1%.
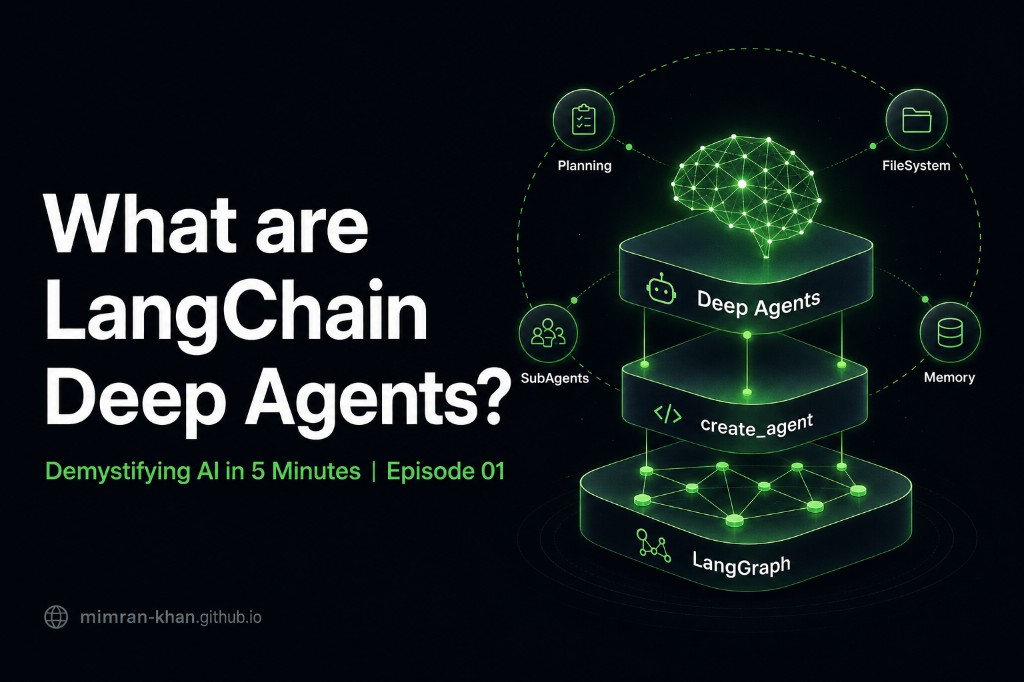
What are LangChain Deep Agents?
LangChain shipped something that makes CrewAI and AutoGen look like toys. Nobody noticed.
Is Grep All You Need? Agent Harness Paper
Grep beats vector search inside AI agents. The results broke everyone's assumptions.

LongCat-2.0: Open-Source 1M Context That Beats GPT-5.5
Meituan just dropped a 1.6T parameter model with 1M token context. MIT licensed. It outperforms GPT-5.5 on SWE-bench Pro.
Next Episode
Next episode dropping soon
New episodes every Mon, Wed, Sat. Follow on LinkedIn to get notified when the next one drops.
Never miss an episode
New episodes drop Mon, Wed, Sat. Follow for updates.